Data processing at scale. Built for geospatial.
Build, run and share data pipelines in your browser, from a library of geospatial blocks you can extend in any language.
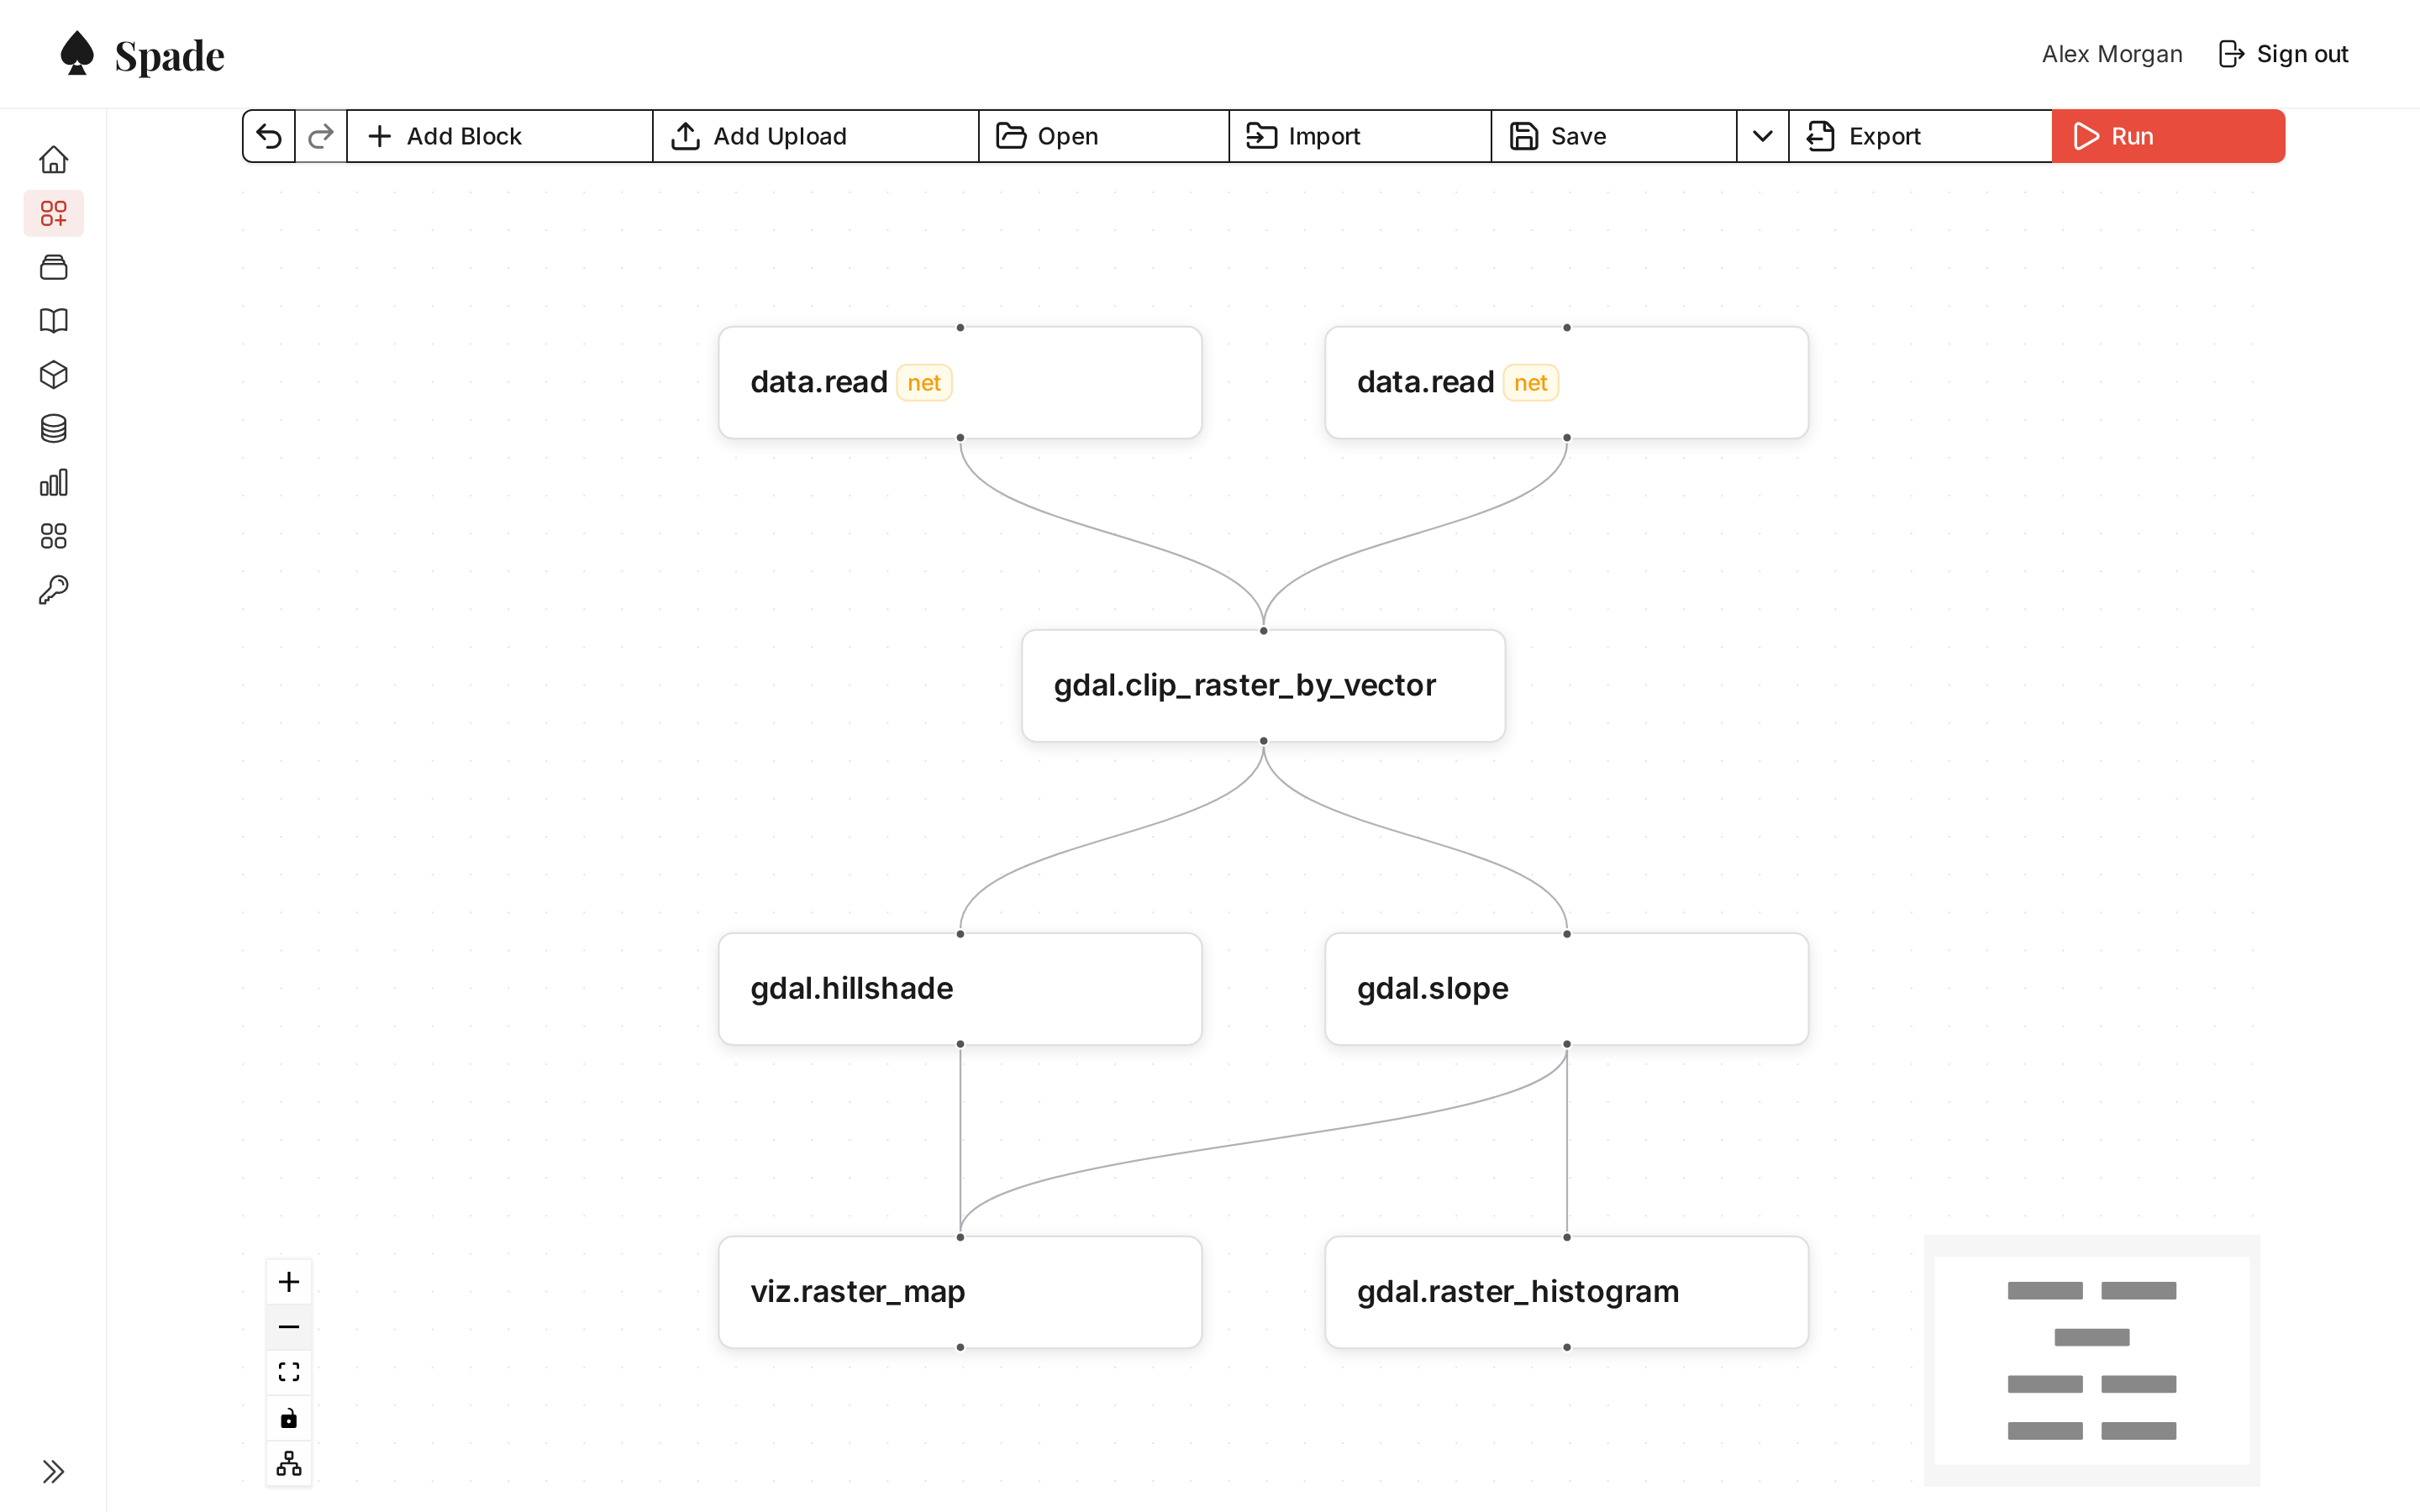
What is Spade?
Spade is a data processing system designed for massive data with first-class geospatial support. It lets you build complex workflows by connecting reusable, isolated computational blocks.
Processing steps are independent blocks that execute in isolation — each one a subprocess with typed inputs and outputs, sandboxed when running in the cloud. Write them in Python, R, Go, Rust, or TypeScript.
Define your workflows as declarative YAML pipelines. The scheduler resolves dependencies and executes blocks in parallel, handling caching and map/reduce fan-out automatically — a block failure halts the pipeline immediately with full logs preserved, rather than continuing on corrupted state.
Your Pipelines, in the Browser
Find the blocks you need, run pipelines in the cloud, and see the results the moment they are ready. No code and nothing to install.
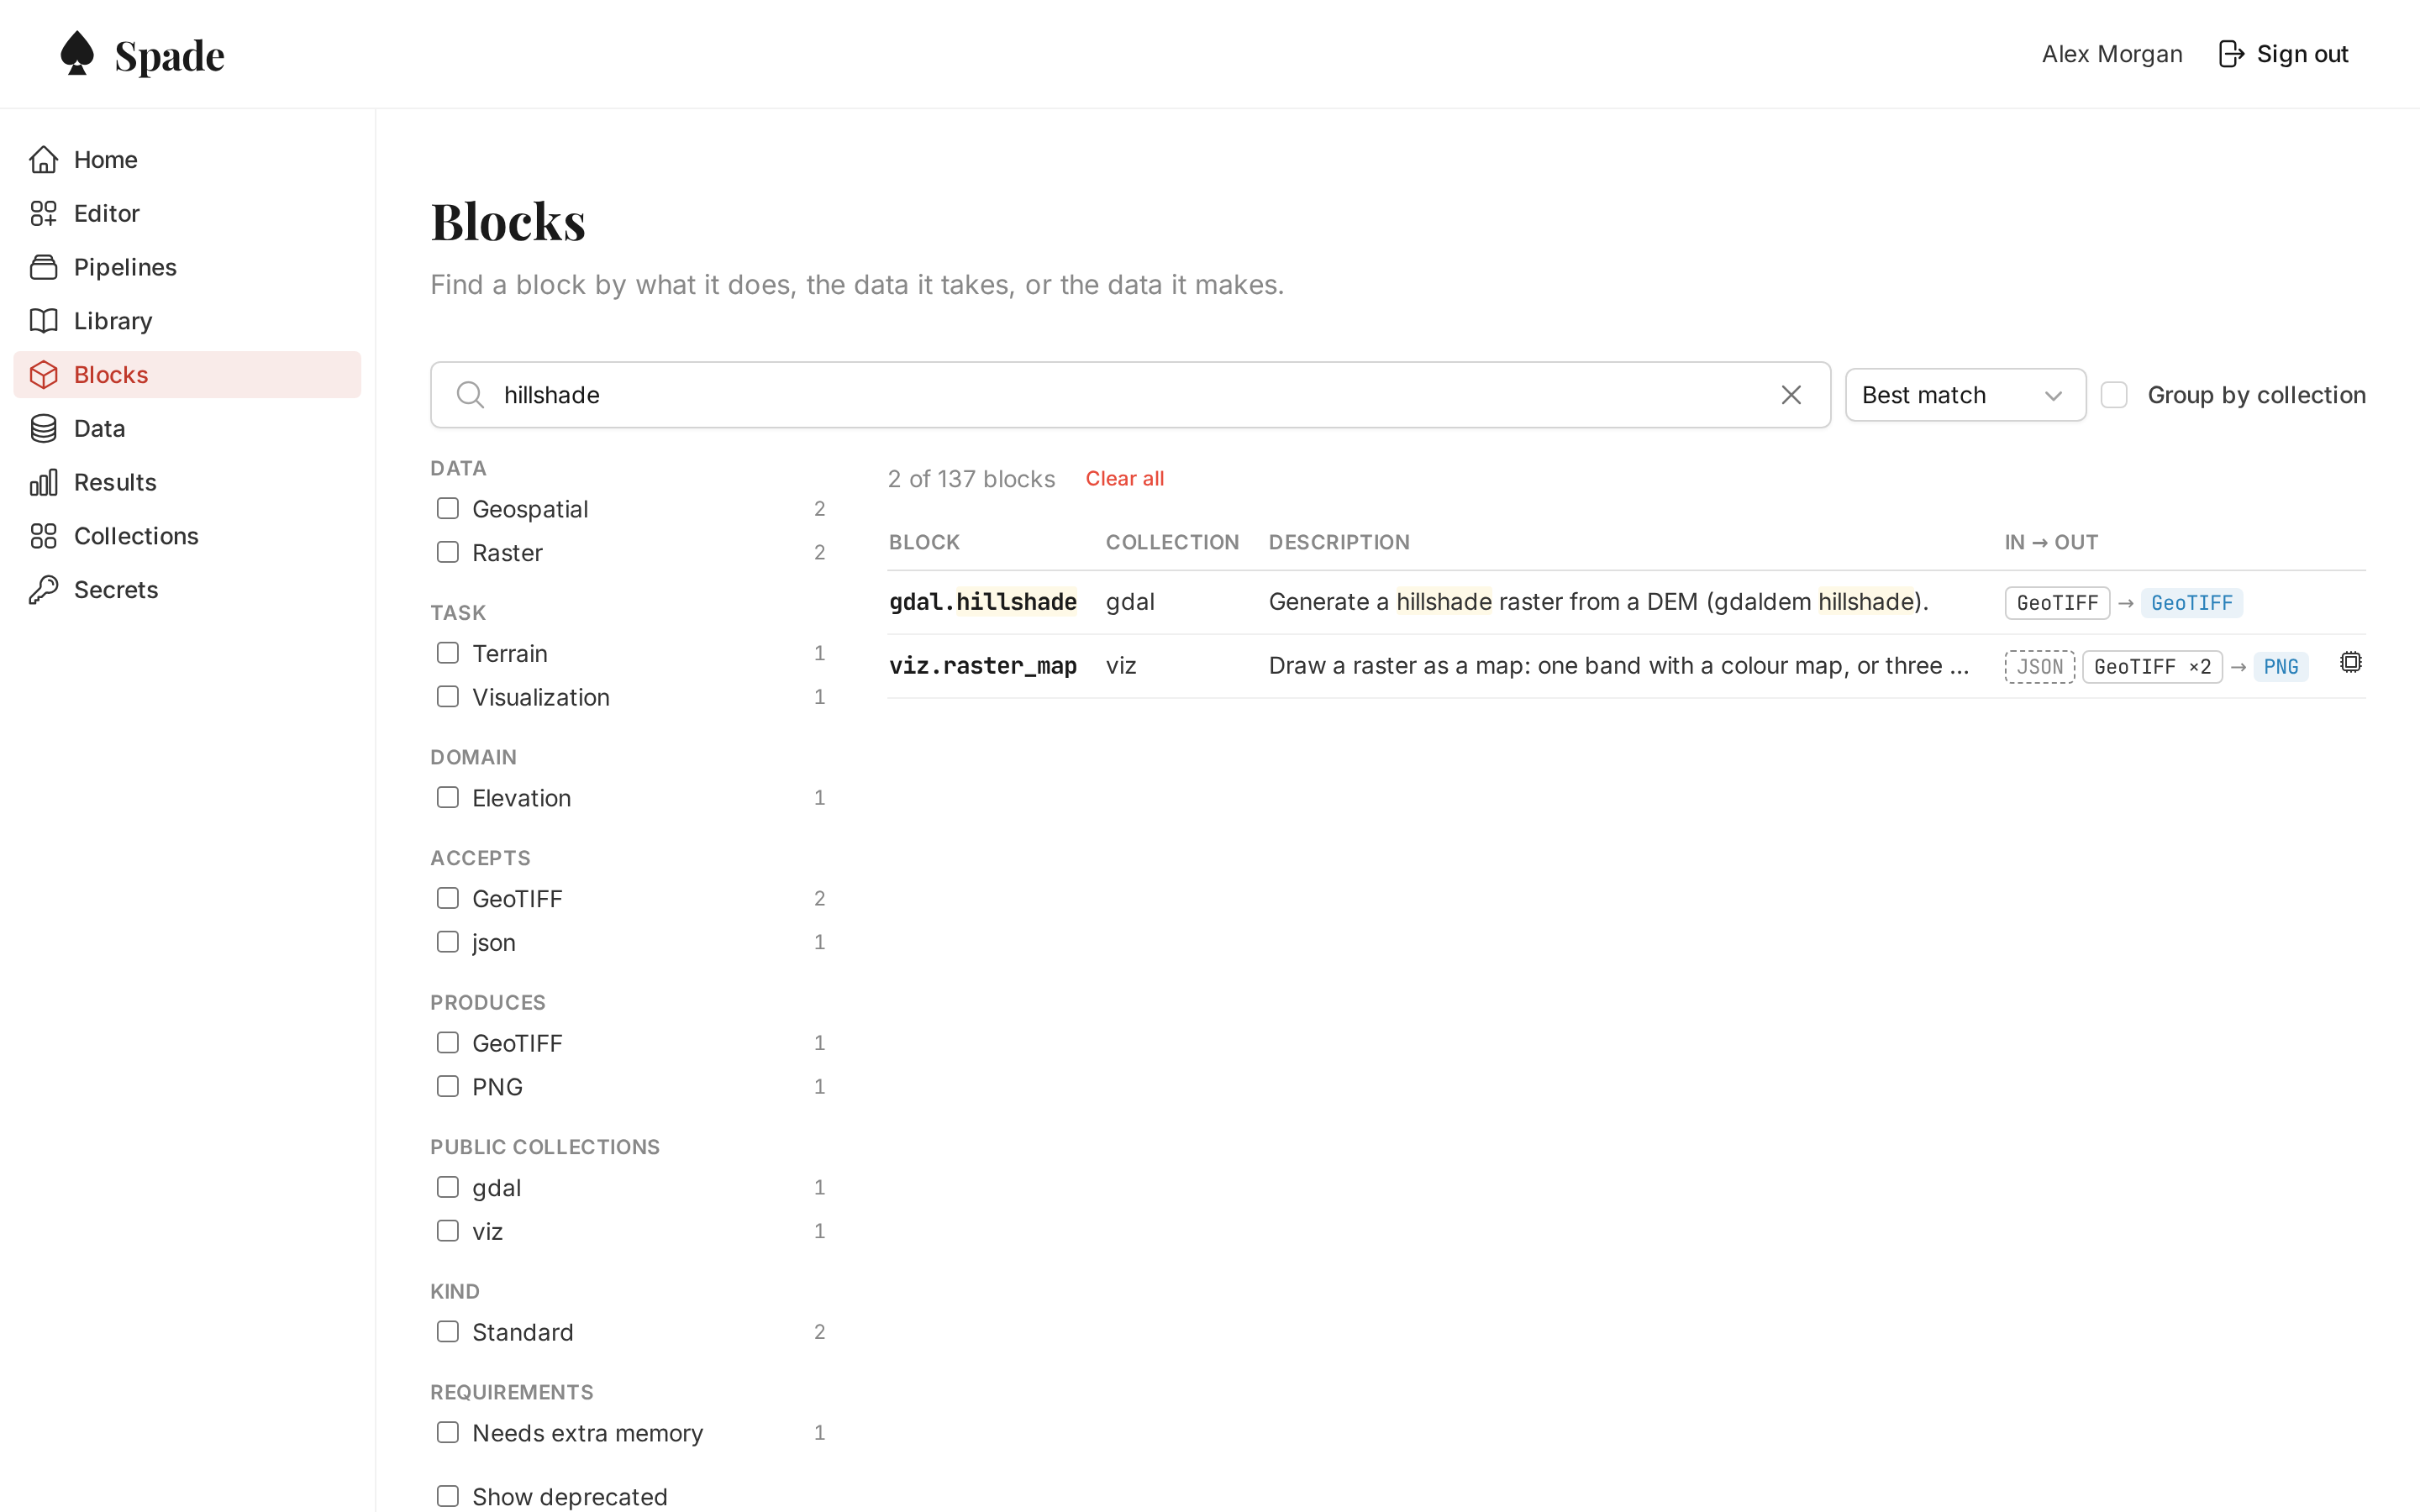
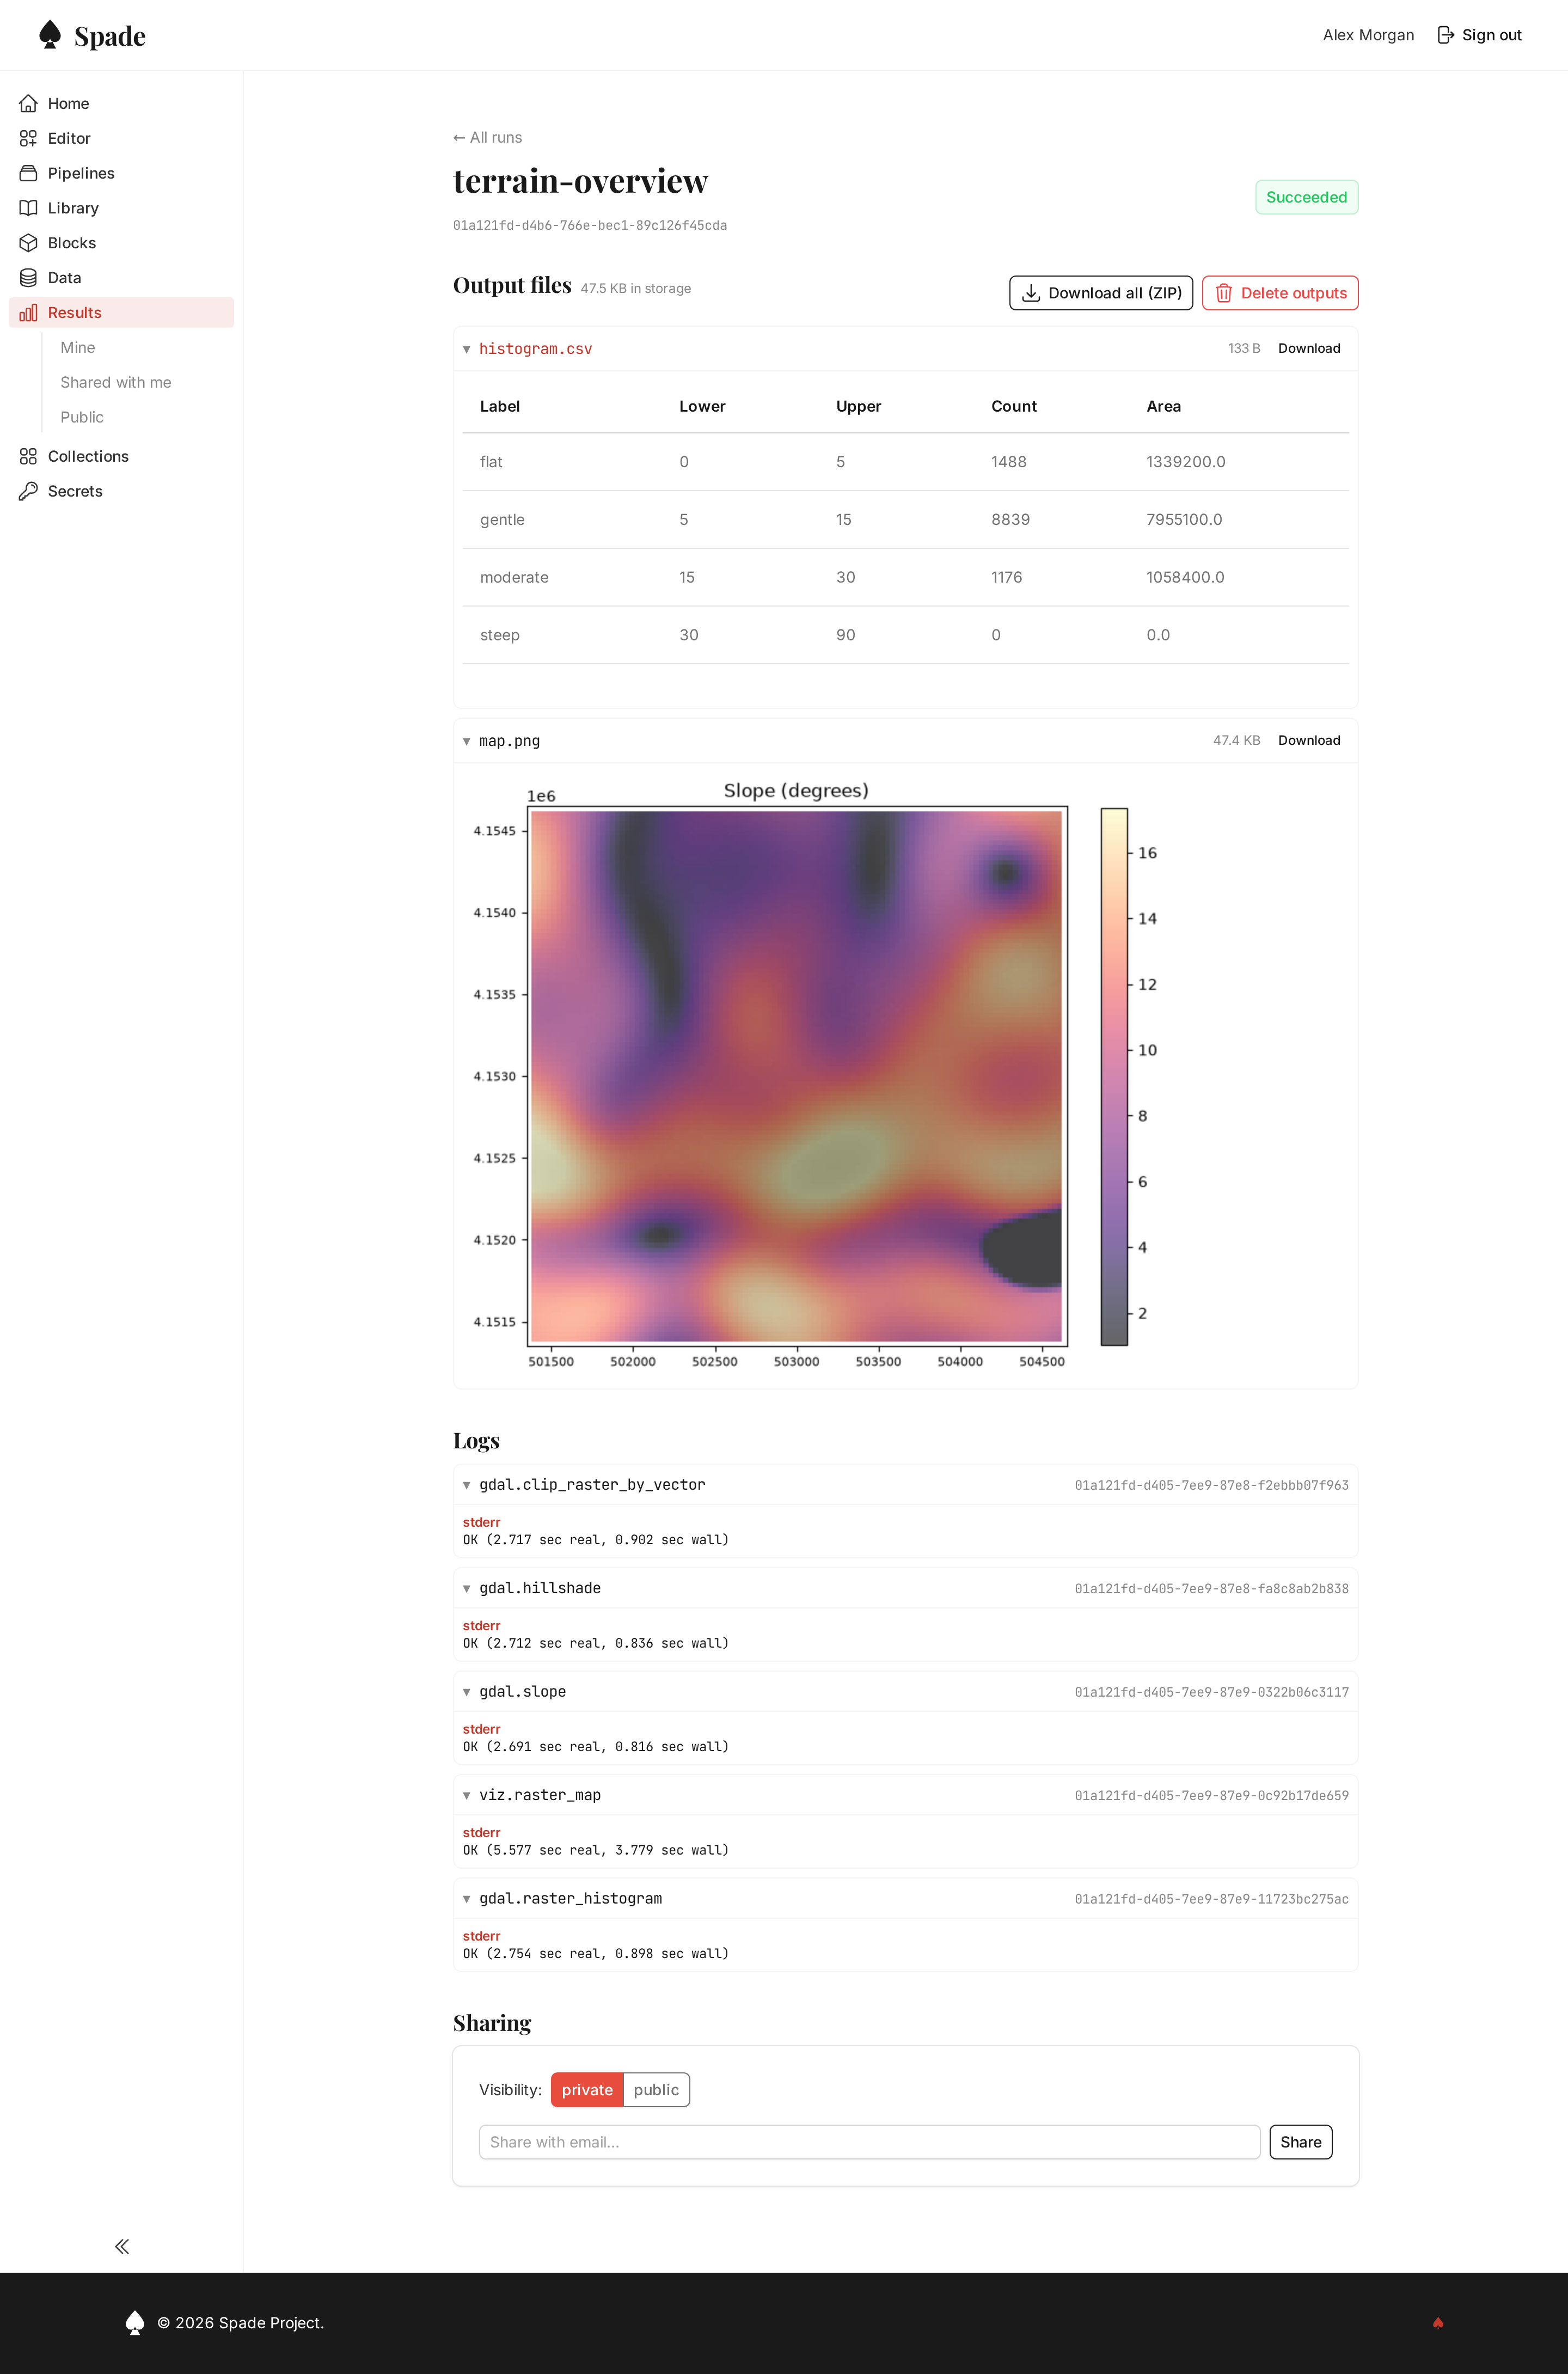
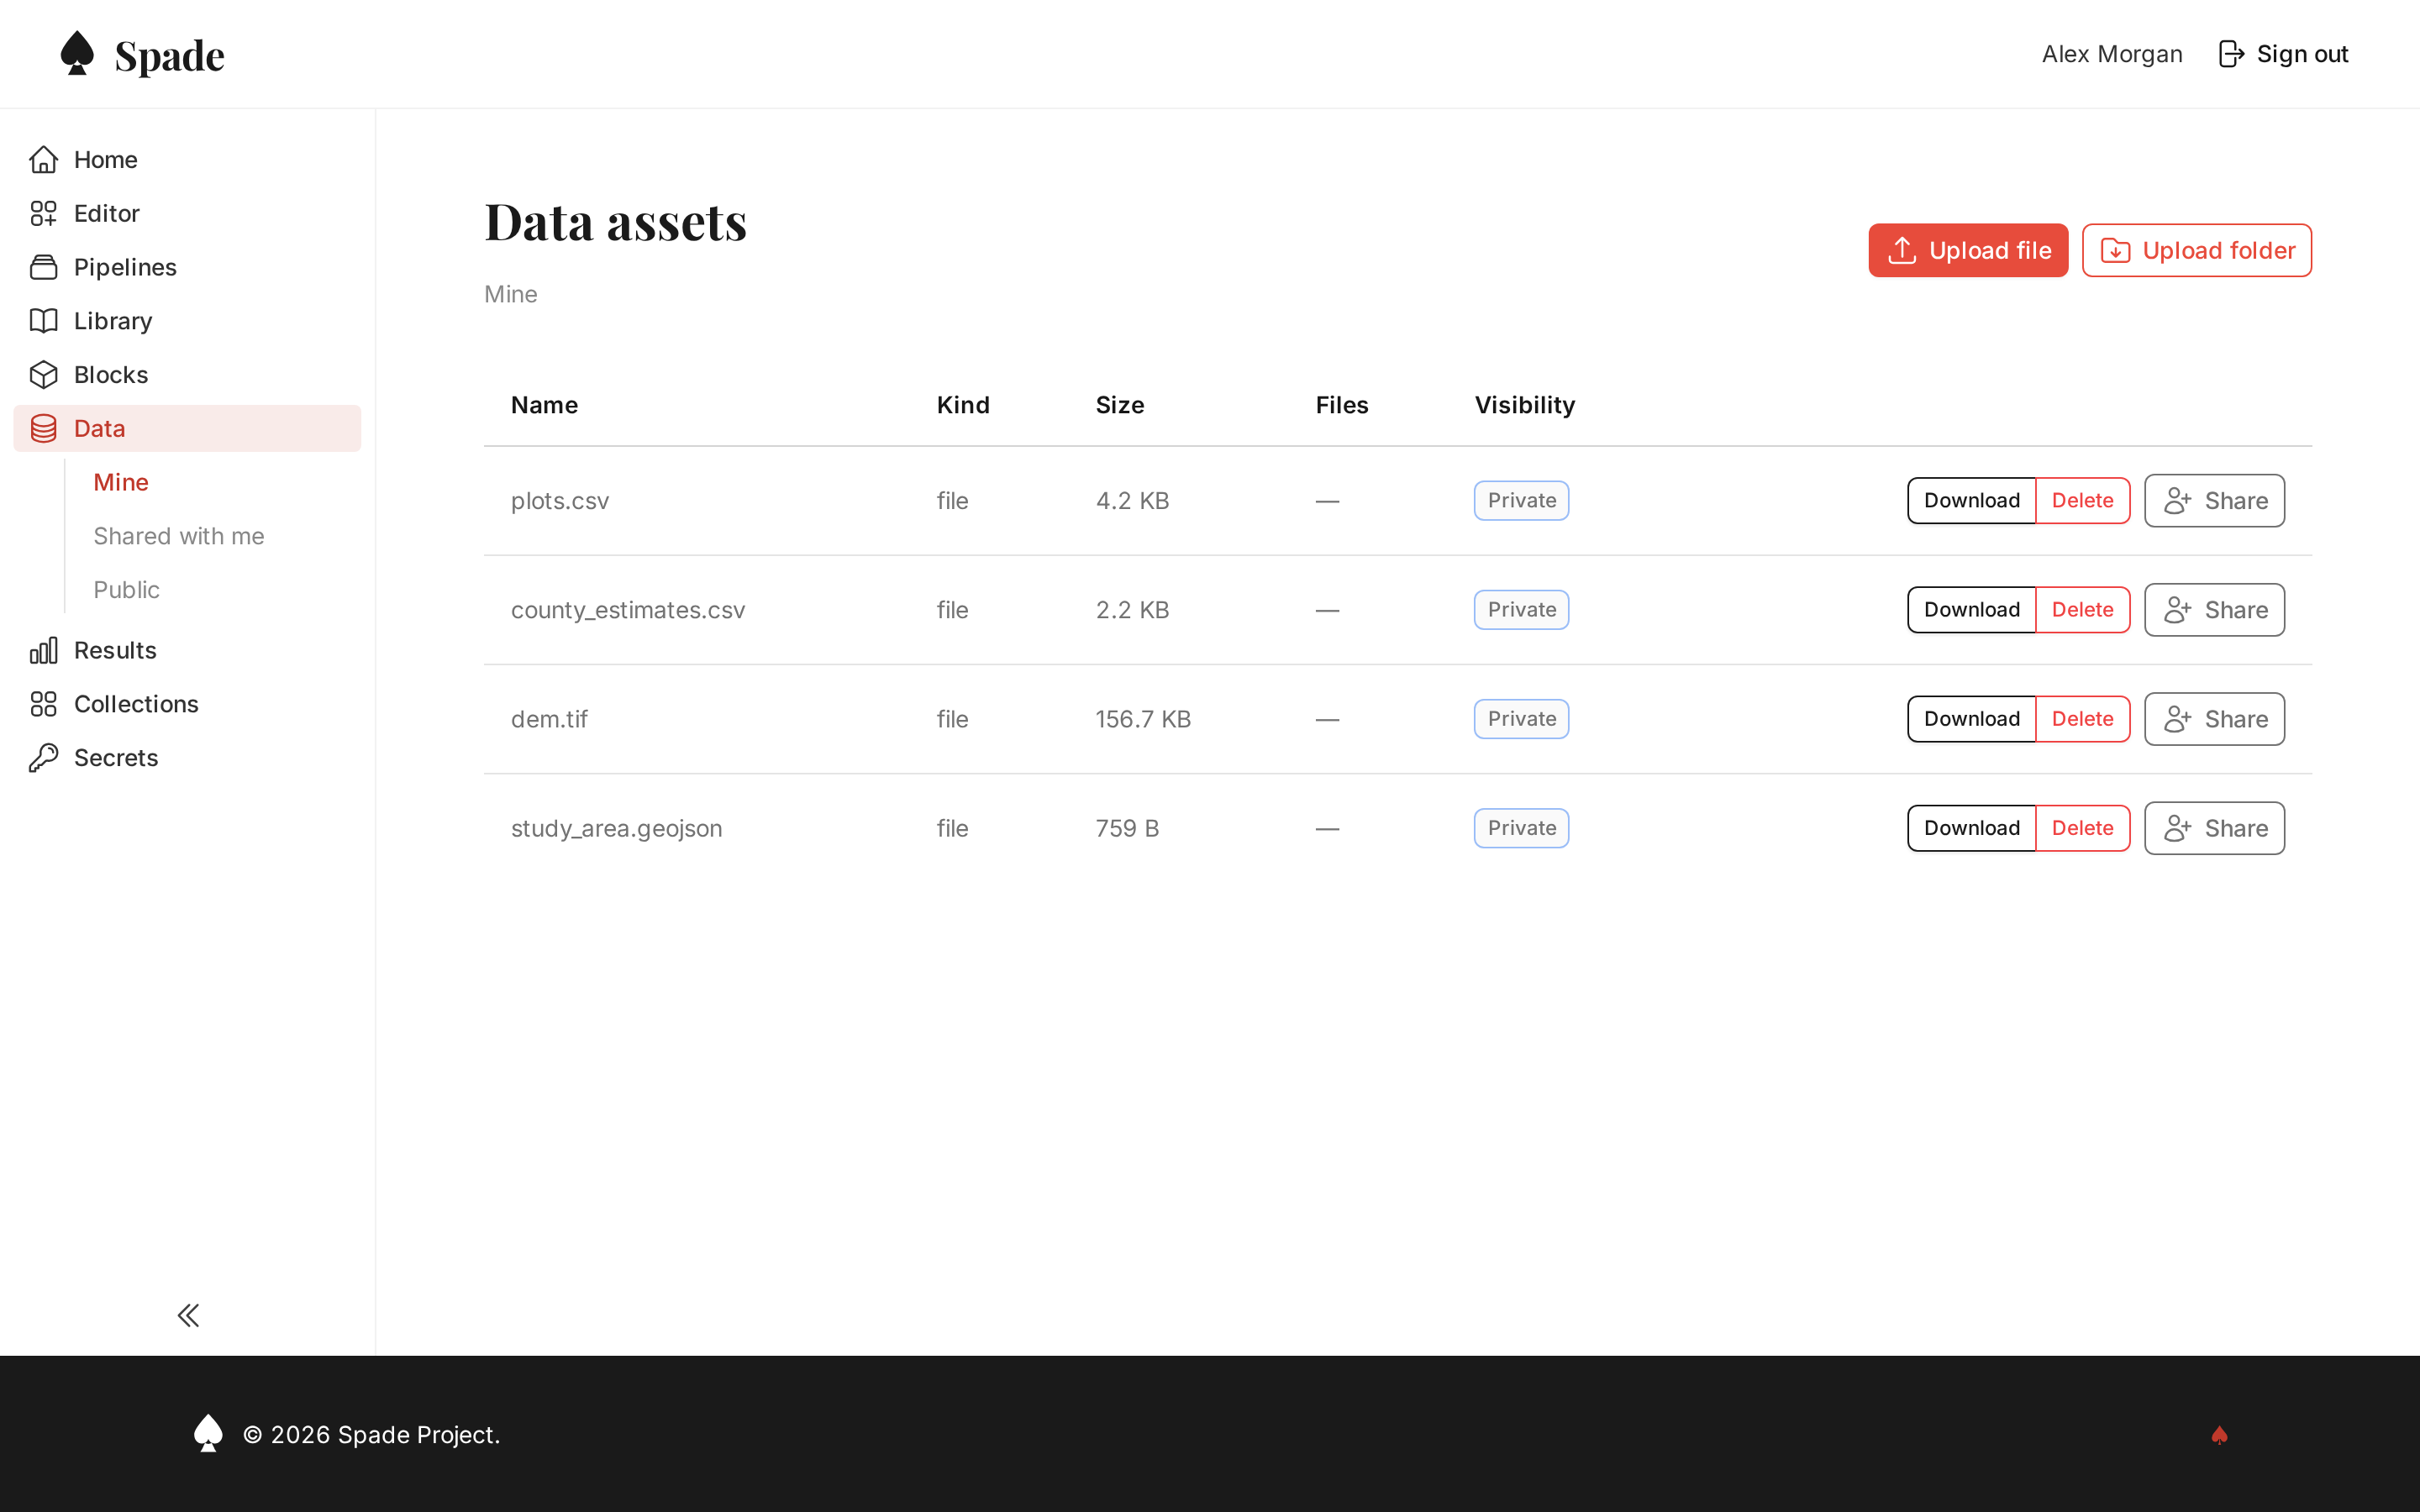
Rather just ask? Connect Claude or another AI assistant and it will find the blocks, build the pipeline and run it for you.
Deal Yourself a Winning Hand
Everything you need to build, run, and scale data processing pipelines.
Web UI
Build, run and share pipelines in the browser, with no code required.
Declarative Pipelines
Define workflows as YAML. The scheduler resolves dependencies and parallelizes execution.
Geospatial First
Native support for raster, vector, and tabular geospatial data through GDAL integration.
Map/Reduce at Scale
Fan out across collections and reduce results back together, automatically.
Secure by Default
Network access is restricted by default, with full filesystem/process sandboxing when blocks run in the cloud.
Multi-Language Blocks
Write blocks in Python, R, Go, Rust, or TypeScript. Spade handles the rest.
Built for Real-World Data
Remote Sensing
Processing satellite imagery at scale, including reprojection, tiling, and analysis across massive raster datasets.
Learn More →Geospatial ETL
Extracting, transforming, and loading spatial datasets across formats and coordinate systems at any scale.
Learn More →Scientific Pipelines
Reproducible research workflows combining data from multiple providers and processing steps.
Learn More →Build Your Own Blocks
A block is a plain function in the language you already use. Spade loads its inputs, runs it in isolation, and handles everything in between.
Write a block
Typed inputs and outputs, automatic parameter loading, and no boilerplate.
from spadelib import run, RasterFile

def handler(source: RasterFile) -> RasterFile:
    # Your processing logic here
    return RasterFile(path=result)

if __name__ == "__main__":
run(handler)library(spadelib)
handler <- function(source) {
# Your processing logic here
RasterFile(path = result)
}
spade_types(handler) <- list(source = "RasterFile", .return = "RasterFile")
run(handler)import { run, spadeBlock, RasterFile } from "spadelib";
const handler = spadeBlock({
inputs: { source: RasterFile },
output: RasterFile,
})(function handler({ source }: { source: RasterFile }) {
// Your processing logic here
return new RasterFile(resultPath);
});
await run(handler);package main
import "github.com/krbundy/spadelib"
func handler(args *spadelib.Args) (*spadelib.RasterFile, error) {
source, err := spadelib.Input[*spadelib.RasterFile](args, "source")
if err != nil {
return nil, err
}
// Your processing logic here
result := spadelib.NewRasterFile(resultPath)
return &result, nil
}
func main() {
spadelib.Run(handler)
}use spadelib::{run, Args, RasterFile};
fn handler(args: Args) -> Result<RasterFile, Box<dyn std::error::Error + Send + Sync>> {
let source: RasterFile = args.input("source")?;
// Your processing logic here
Ok(RasterFile::new(result_path))
}
fn main() {
run(handler);
}Wire it into a pipeline
Write the pipeline in YAML, or drop the block onto the editor’s canvas.
name: terrain
version: "1.0"
blocks:
  - id: "@dem"
    name: data.read
    inputs: []
    args:
      uri: s3://bucket/dem.tif
  - id: "@shade"
    name: gdal.hillshade
    inputs: ["@dem"]
    args:
azimuth: 315Run it
Locally with the CLI, or in the cloud, where every block runs sandboxed. Unchanged steps come from the cache.
$ spade run pipeline.yaml
  [1/2] data.read (cached)
  [2/2] gdal.hillshade running...
  [2/2] gdal.hillshade complete

Pipeline complete: 2 block(s)
  executed (1 cached) in 2.1s
Start a collection
$ spade setup
$ spade init --language python
$ spade add my_block
$ spade install .
$ spade run pipeline.yamlReady to Play?
Sign in and build your first pipeline in minutes.